Exercises 7
Exercise 7.1
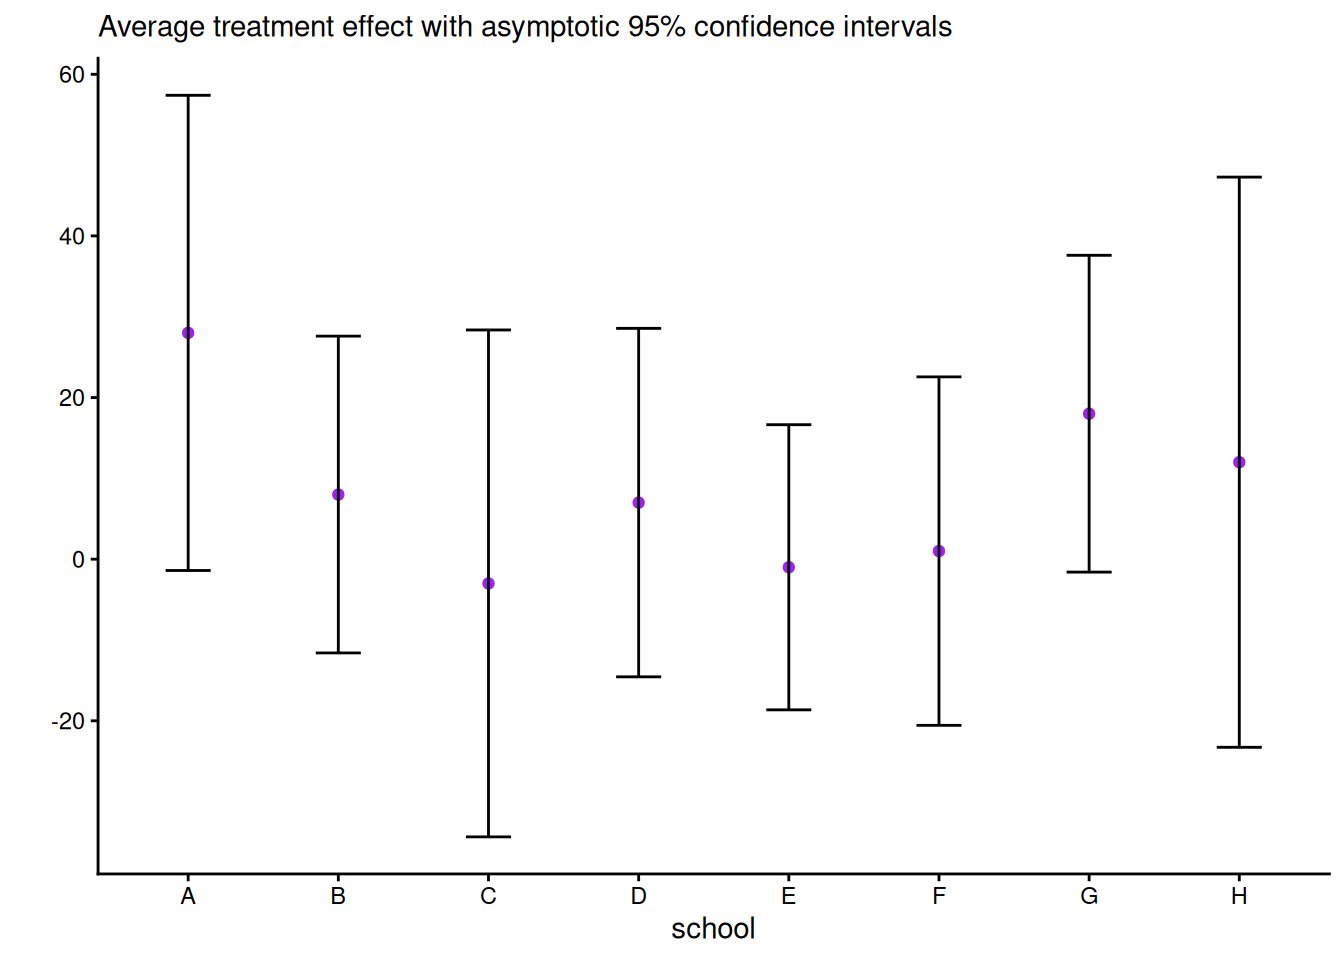
Consider the eight school data from Educational Testing Service (ETS), featured prominently in Gelman et al. (2013). The data shows results of randomized experiments in eight different schools to estimate the effect of coaching on SAT-V scores. The data consist of estimated treatment mean difference and their standard errors. The data size are large, so the average treatment effect (ATE) can be considered Gaussian and the standard errors are treated as a known quantity.
Consider a one-way ANOVA with a single observation per group, where for \(i=1, \ldots, n,\) we have \[\begin{align*} Y_{i} &\sim \mathsf{Gauss}(\mu + \alpha_i, \sigma^2_i) \\ \alpha_i &\sim \mathsf{Gauss}(0, \sigma^2_\alpha) \end{align*}\] and an improper prior for the mean \(p(\mu) \propto 1.\) If there are \(K\) groups, then the group-specific mean is \(\mu+\alpha_k\), and there is a redundant parameter. In the Bayesian setting, the parameters are weakly identifiable because of the prior on \(\boldsymbol{\alpha}\), but the geometry is such that \(\alpha_k \to 0\) as \(\sigma^2_{\alpha} \to 0.\) See Section 5.5 on p. 119 of Gelman et al. (2013) for more details.
We fit the model by adding redundant parameter to improve mixing (Gelman et al., 2008) \[\begin{align*} Y_{i} &\sim \mathsf{Gauss}(\mu + \alpha\xi_i, \sigma^2_i) \\ \xi_i &\sim \mathsf{Gauss}(0, \sigma^2_\xi) \end{align*}\] so that \(\sigma_\alpha = |\alpha|\sigma_\xi.\)
# Eight school data
es <- data.frame(school = LETTERS[1:8],
                 y = c(28, 8, -3, 7, -1, 1, 18, 12),
                 se = c(15, 10, 16, 11, 9, 11, 10, 18))
Derive the Gibbs sampler for the two models with improper priors. Note that, to sample jointly from \(p(\mu, \boldsymbol{\alpha} \mid \boldsymbol{y}, \sigma^2_{\alpha}, \boldsymbol{\sigma}^2_{\boldsymbol{y}})\), you can draw from the marginal of \(\boldsymbol{\alpha}\), then the conditional \(\mu \mid \boldsymbol{\alpha}, \cdots\).
Fit the three algorithms described in Gelman et al. (2008) and compare their efficiency via effective sample size (ESS). In particular, draw traceplots and calculate effective sample sizes for
- \(\mu\)
- \(\alpha_1\),
- the sum \(\mu + \alpha_1\).
as well as pairs plot of \(\alpha_i, \log \sigma_{\alpha}\). The latter should display a very strong funnel.
See this post for display of the pathological behaviour that can be captured by divergence in Hamiltonian Monte Carlo.
References
Gelman, A., Carlin, J. B., Stern, H. S., Dunson, D. B., Vehtari, A., & Rubin, D. B. (2013). Bayesian data analysis (3rd ed.). Chapman; Hall/CRC. https://doi.org/10.1201/b16018
Gelman, A., Dyk, D. A. van, Huang, Z., & Boscardin, J. W. (2008). Using redundant parameterizations to fit hierarchical models. Journal of Computational and Graphical Statistics, 17(1), 95–122. https://doi.org/10.1198/106186008x287337